Local decision models with AI SDK Ollama
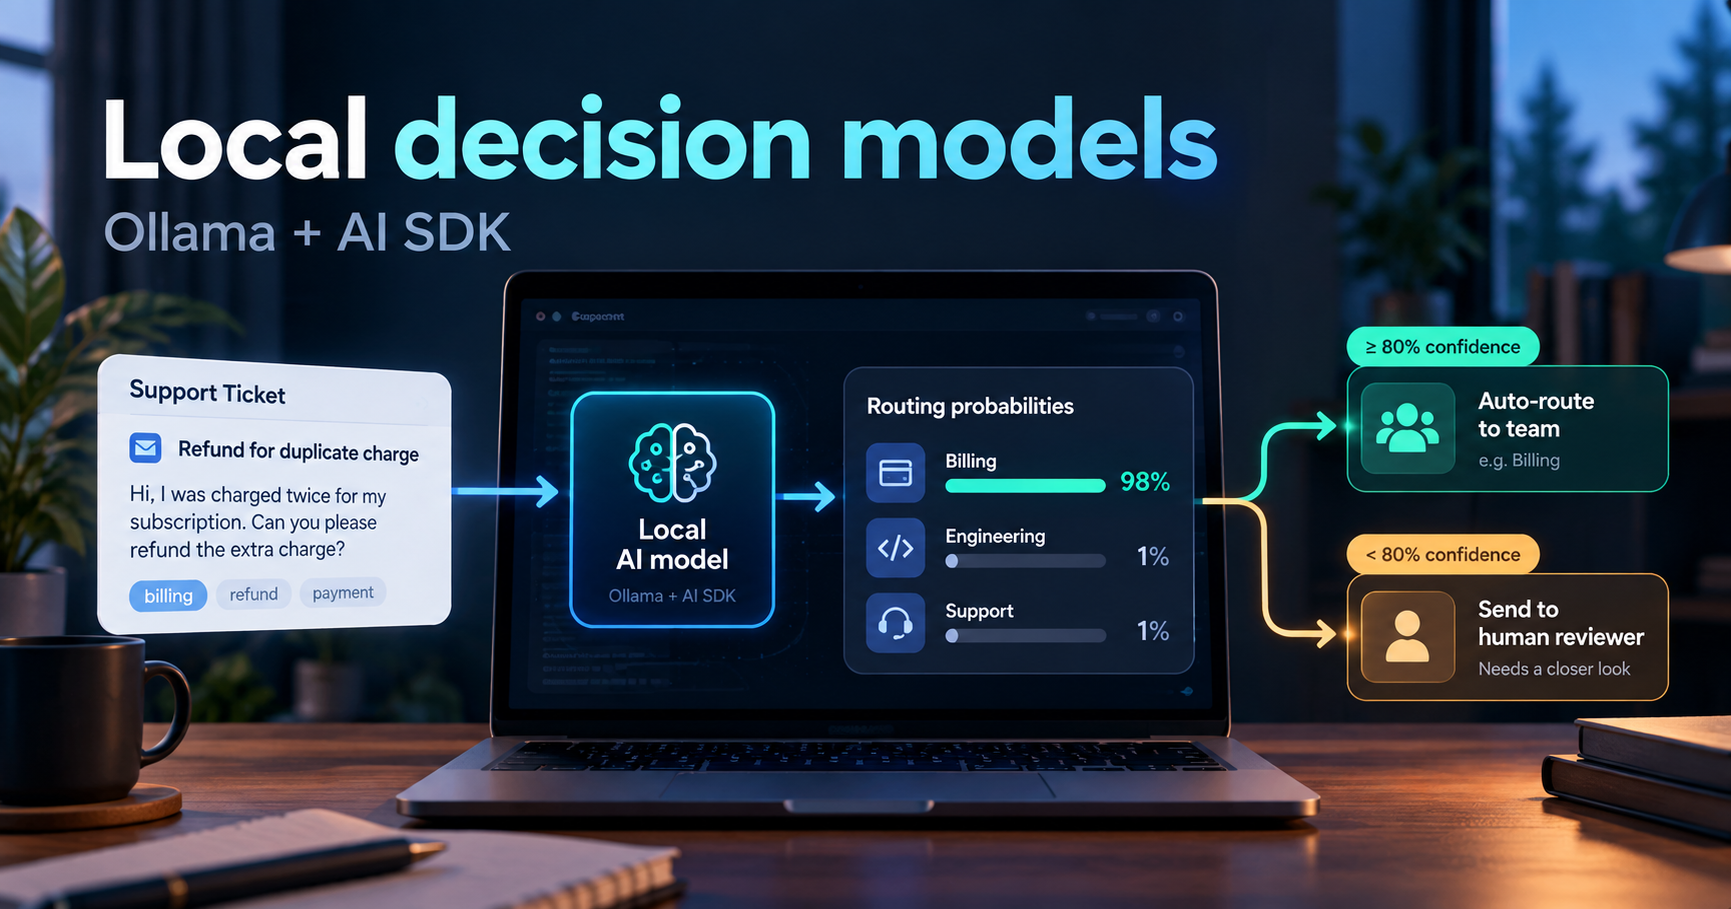
01 Oct 2026Ollama 0.35 runs decision models on your own computer. You give one a support ticket and a question like “which team should handle this?”, and it returns a percentage for each team instead of writing a reply.
ai-sdk-ollama 4.4.0 lets you call them from the AI SDK.
I ran 12 support tickets through the three new models and a small chat model on a MacBook Pro.
The decision models routed every clear ticket correctly.
On the tickets I wanted a person to check, two of the three models still sounded sure, and that changes how you set the rule that hands work to a human.
Why run decision models locally?
A support team reads each incoming ticket and decides who owns it: billing, engineering, or the help desk.
You can hand that sorting to a general-purpose language model, but it still has to generate an answer.
Unless it runs on your own machine, each call also adds network time and, in most setups, a usage fee.
A decision model does one narrow job. You give it the ticket, the question, and the list of possible answers. It writes nothing. It returns a percentage for each answer: billing 98%, engineering 1%, help desk 1%.
Your software then applies a rule you write down in advance, such as “route it automatically if the top answer is 70% or higher, otherwise send it to a person”.
---
alt: "A support ticket goes to a decision model, which returns a percentage for each team. A rule checks the top percentage: 70% or higher routes the ticket to that team automatically; below 70% sends it to a person."
---
flowchart LR
  T["Support ticket<br/><i>I was charged twice</i>"] --> M["Decision model<br/>on your computer"]
  M --> P["billing 98%<br/>engineering 1%<br/>help desk 1%"]
  P --> R{"Top answer<br/>70% or higher?"}
  R -- yes --> A["Route to billing<br/>automatically"]
  R -- no --> H["Send to a person<br/>to check"]
With Ollama the model runs on your own machine. You pay no per-call model fee, and the ticket text never has to leave your network. The rule only protects you if the percentage drops when the ticket is unclear. A model that says 95% on a ticket a person should have read sends it straight to the wrong queue, and nobody looks. My benchmark tests for that case.
What Ollama shipped
TypeSafe’s Jev is a hosted model that writes no text and answers typed questions about some state with probabilities. On 29 September, Ollama announced the same API, served locally on /v1/systemone, with three models:
| Model | From | Size on disk |
|---|---|---|
nimble |
Bespoke Labs, 9B, open source | 9.5 GB |
tev1 |
Together AI, 4B, experimental | 4.5 GB |
tev1:0.8b |
Together AI, 0.8B, experimental | 811 MB |
The raw request takes a model, the state and named questions. A boolean question uses TypeSafe’s name for it, noul:
curl http://localhost:11434/v1/systemone -d '{
  "model": "tev1:0.8b",
  "state": { "ticket": "I was charged twice. Please refund the extra payment." },
  "questions": {
    "refund": { "type": "noul", "instructions": "Does the customer explicitly ask for a refund?" }
  }
}'
{
"model": "tev1:0.8b",
"answers": { "refund": { "type": "noul", "noul": 0.8475492733267009 } },
"usage": { "input_tokens": 123, "output_tokens": 1 }
}Calling them from the AI SDK
I released ai-sdk-ollama 4.4.0 on 30 September with support for them.
ollama.evaluationModel(id) implements the AI SDK’s experimental evaluation model spec on top of the ollama client’s systemone() method. You write the same evaluate call you would write for Jev, and your questions run on your machine:
ollama pull nimble
pnpm add ai ai-sdk-ollama
import { experimental_evaluate as evaluate } from 'ai';
import { ollama } from 'ai-sdk-ollama';
const { answers, providerMetadata } = await evaluate({
model: ollama.evaluationModel('nimble'),
state: { ticket },
questions: {
team: {
type: 'choice',
instructions: 'Which team should handle `ticket`?',
criteria: {
billing: 'Charges, invoices, refunds.',
engineering: 'Bugs, errors, outages, data loss.',
support: 'How-to questions and account help.',
},
},
refund: { type: 'boolean', instructions: 'Does `ticket` explicitly ask for a refund?' },
urgency: { type: 'score', instructions: 'How urgent is `ticket`?', criteria: ['Routine', 'Soon', 'Urgent'] },
},
});
// Your policy stays in code: a close race goes to a human.
const p = answers.team.probabilities?.[answers.team.choice] ?? 0;
const queue = p < 0.7 ? 'triage' : answers.team.choice;
const priority = answers.urgency.score >= 1.5 ? 'p1' : 'p2';The provider translates AI SDK boolean questions into Ollama’s noul, so answers.refund.probability holds P(yes). Ollama also returns a confidence figure for choice and score answers, and the provider puts it in providerMetadata.ollama.confidence. Ollama defines it as how concentrated the probabilities are, and says it is not the chance that the answer is right. On the invoice ticket below, nimble put engineering at 0.84 and reported confidence of 0.50. The policies in this post use the probabilities. If you inject your own Ollama client, it needs a systemone() method, which ollama 0.6.4 provides.
On four tickets, nimble answered all three questions in one call each:
I was charged twice this month. Please refund the extra payment.
  queue=billing priority=p2 team=billing@0.98 refund=1.00 urgency=0.77/2

Checkout has returned 500 errors since 9am and we are losing sales!
  queue=engineering priority=p1 team=engineering@0.92 refund=0.01 urgency=1.97/2

How do I export my data to CSV?
  queue=support priority=p2 team=support@0.99 refund=0.00 urgency=0.19/2

Your app deleted my invoices after the update and I need them for my accountant tomorrow.
  queue=engineering priority=p1 team=engineering@0.84 refund=0.01 urgency=1.80/2
In business terms: the double charge goes to billing, the checkout outage goes to engineering as high priority, and the how-to question goes to the help desk, labelled support in the code. The model answered three questions about each ticket at once: which team, whether the customer wants a refund, and how urgent it is.
Each three-question call took about 1.9 seconds on my M1 Pro, for roughly 900 input tokens (the pieces of text the model reads) and 4 output tokens. The first call took 8 to 13 seconds across runs, because Ollama loaded 9.5 GB into memory before answering.
Twelve tickets, four models
I wanted numbers for a question I care about more than the headline accuracy: when I want a ticket escalated, does the model’s probability warn me? So I wrote 12 tickets. Nine have one right team. Three are ambiguous on purpose, and I expect the policy to send them to triage:
bug-refund: “The sync bug lost a week of my data, so I want my money back for this month.”seat-count: “We removed three seats but the plan page still shows twelve. Is that a display bug or will we be billed?”vague: “It is not working again. Sort it out.”
Each model answered one choice question per ticket, three passes. I also ran granite4.2:3b, a chat model, through the AI SDK’s EvaluationLanguageModel adapter. The adapter packs the questions into one structured-output call and asks the model to report its own probabilities.
In the table, “policy match” means the ticket ended up where I wanted it: the right team for a clear ticket, or a person for an unclear one.
Before each model runs, the script calls ollama stop on it. That clears any prompt cache from an earlier run, so pass 1 measures a ticket the model has not seen. Passes 2 and 3 repeat identical prompts, so Ollama can reuse the cached prompt prefix and skip most of the prefill work. I report those latencies separately.
| Model | Policy match | Same answer every pass | Median time, new ticket | Median time, repeated ticket | Policy misses |
|---|---|---|---|---|---|
| nimble | 27/36 (9/12 tickets) | 100% | 928 ms | 107 ms | bug-refund → billing @ 0.95, seat-count → billing @ 0.80, vague → engineering @ 0.91 |
| tev1 | 30/36 (10/12 tickets) | 100% | 415 ms | 67 ms | bug-refund → billing @ 0.74, vague → engineering @ 0.96 |
| tev1:0.8b | 27/36 (9/12 tickets) | 100% | 97 ms | 39 ms | bug-refund → engineering @ 0.82, seat-count → billing @ 0.77, vague → engineering @ 0.85 |
| granite4.2:3b | 17/36 (5/12 tickets on every pass) | 67% | 562 ms | 552 ms | 19 decisions across seven tickets, every one @ 1.00 |
“Policy match” counts the 36 decisions (12 tickets, three passes) where the routed decision matched the expected one: the labelled team for the nine clear tickets, and triage for the three ambiguous ones. A policy miss on an ambiguous ticket can still name a defensible team. The miss is that the model sounded too sure for the ticket to reach a human. The ticket count in brackets counts tickets that matched on all three passes. The decision models never changed an answer between passes, so their two counts agree. granite matched 7 of the 12 tickets at least once, and only 5 on every pass.
All three decision models got the nine clear tickets right
Each model answered the same way on all three passes, and across four runs of the script, including one after I upgraded ai to 7.0.124. The probabilities matched to two decimal places each time. granite matched the policy on 14, 19, 18 and 17 of 36 decisions across the same four runs, and filed a double charge under engineering in one run and support in another.
Only one ambiguous ticket reached a human
---
alt: "The three unclear tickets as tev1 handled them. The seat count ticket scored billing 53%, below the 70% rule, and went to a person. The bug refund ticket scored billing 74% and the vague ticket scored engineering 96%; both went straight to a team with nobody checking."
---
flowchart LR
  S["Seat count ticket<br/>billing 53%"] --> H["Below 70%:<br/>a person checks"]
  B["Bug plus refund ticket<br/>billing 74%"] --> A1["Routed to billing<br/>nobody checks"]
  V["'It is not working again'<br/>engineering 96%"] --> A2["Routed to engineering<br/>nobody checks"]
tev1 sent seat-count to triage with billing at 0.53. The 0.7 threshold did nothing else. nimble put bug-refund in billing at 0.95, and all three models sent “It is not working again. Sort it out.” to engineering at 0.85 or higher.
You can defend some of those answers. A refund request belongs to billing, and a broken product often means engineering. The numbers still matter for your policy. If your policy misses come back at 0.9, a threshold at 0.7 catches none of them. Log the probabilities on your own tickets, look at where the misses land, then choose the number.
The chat model reported 1.00 on every answer
The adapter asks the chat model to report its own probability, and granite reported 1.00 for all 36 answers, including the 19 policy misses. That result covers self-reported numbers through this adapter on this model. It says nothing general about granite. Your threshold still has nothing to compare against. granite also took longer per ticket than tev1, and ran no faster on repeats, because it generates JSON each time.
Latency depends on your hardware and your prompts
Ollama’s Pac-Man demo shows nimble at 91 ms per decision on an M5 Max. On my M1 Pro, a ticket nimble had not seen took about a second, and tev1:0.8b took under 100 ms.
Repeated prompts dropped every decision model to between 39 and 107 ms, so a benchmark that loops over the same few inputs will flatter them.
The models answer faster when they have seen the same text before, so a test that repeats a handful of tickets makes them look quicker than they will be on real traffic. Measure with inputs the model has not seen, and keep the model loaded between requests with Ollama’s keep_alive, or the next request pays the load again.
Picking a model
On these twelve tickets, tev1 beat nimble with half the memory and half the latency. Twelve tickets prove little, though. Ollama’s own benchmark covers 3,880 labelled decisions across 13 data sets and puts nimble at 75.7%, tev1 at 73.3% and tev1:0.8b at 63.5%, against 76.0% for Jev 1.13.
For an escalation policy, headline accuracy matters less than where each model’s misses land. You want the model whose uncertainty your policy can use: its misses should come back below your threshold, where a person sees them. On this set, tev1 put one ambiguous ticket at 0.53 and nimble put none below 0.80.
I would start with tev1:0.8b while you write the questions, because it answers in under 100 ms and a bad rubric shows up fast. Then run your labelled cases on tev1 and nimble, and keep the model whose misses come back with lower numbers. The reranking post uses the same provider, if you want local retrieval next to local routing.
If you own the process
You do not have to trust the model on day one. Run it next to the people who route tickets today, record its percentages, and change nothing. After a few weeks you can see where its mistakes land. If they sit at 50% or 60%, a 70% rule catches them and you can automate the rest. If they sit at 90%, raise the rule, pick a different model, or keep a person on that ticket type.
---
alt: "Four steps left to right: run the model alongside your team and change nothing; compare its percentages with what your team decided; set the rule from those numbers; automate the clearest cases first while people keep the rest."
---
flowchart LR
  A["Step 1<br/>Run it alongside<br/>your team"] --> B["Step 2<br/>Compare its<br/>percentages with<br/>their decisions"]
  B --> C["Step 3<br/>Set the rule<br/>from the numbers"]
  C --> D["Step 4<br/>Automate the<br/>clearest cases first"]
The same pattern works for any decision with a short list of answers: which queue, is this message safe to post, does this request need the expensive model. Engineers set it up once, and the rule stays in code where your team can read and change the 70%.
Run it yourself
The triage example and the benchmark are in ai-sdk-ollama-decision-models:
ollama pull nimble && ollama pull tev1 && ollama pull tev1:0.8b && ollama pull granite4.2:3b
pnpm install
pnpm triage tev1
pnpm bench
pnpm bench nimble runs one model. The script writes every row to results/ as JSON, so you can check my numbers or swap in your own tickets.