Your coding agent says the feature works, and the tests pass. You still can’t tell whether it left the code easier or harder to change.
A complexity gate measures every function, gives the same score on every run, and stops complexity growing past limits you agree. For code already over those limits, a ratchet stops it getting any worse. This post explains the two numbers worth measuring and how to put a gate in front of your agent with AutoRatchet.
AWS Emulator serves the AWS APIs from a container on your machine, with no AWS account. We moved our CDK ephemeral environments onto it and tested CloudFormation, SQS, SNS, EventBridge and three kinds of Lambda against it.
AWS’s durable execution test runner runs a Lambda durable function in your test process, skips its waits and lets you answer its callbacks. We used it to test every branch of a payment approval in under a second.
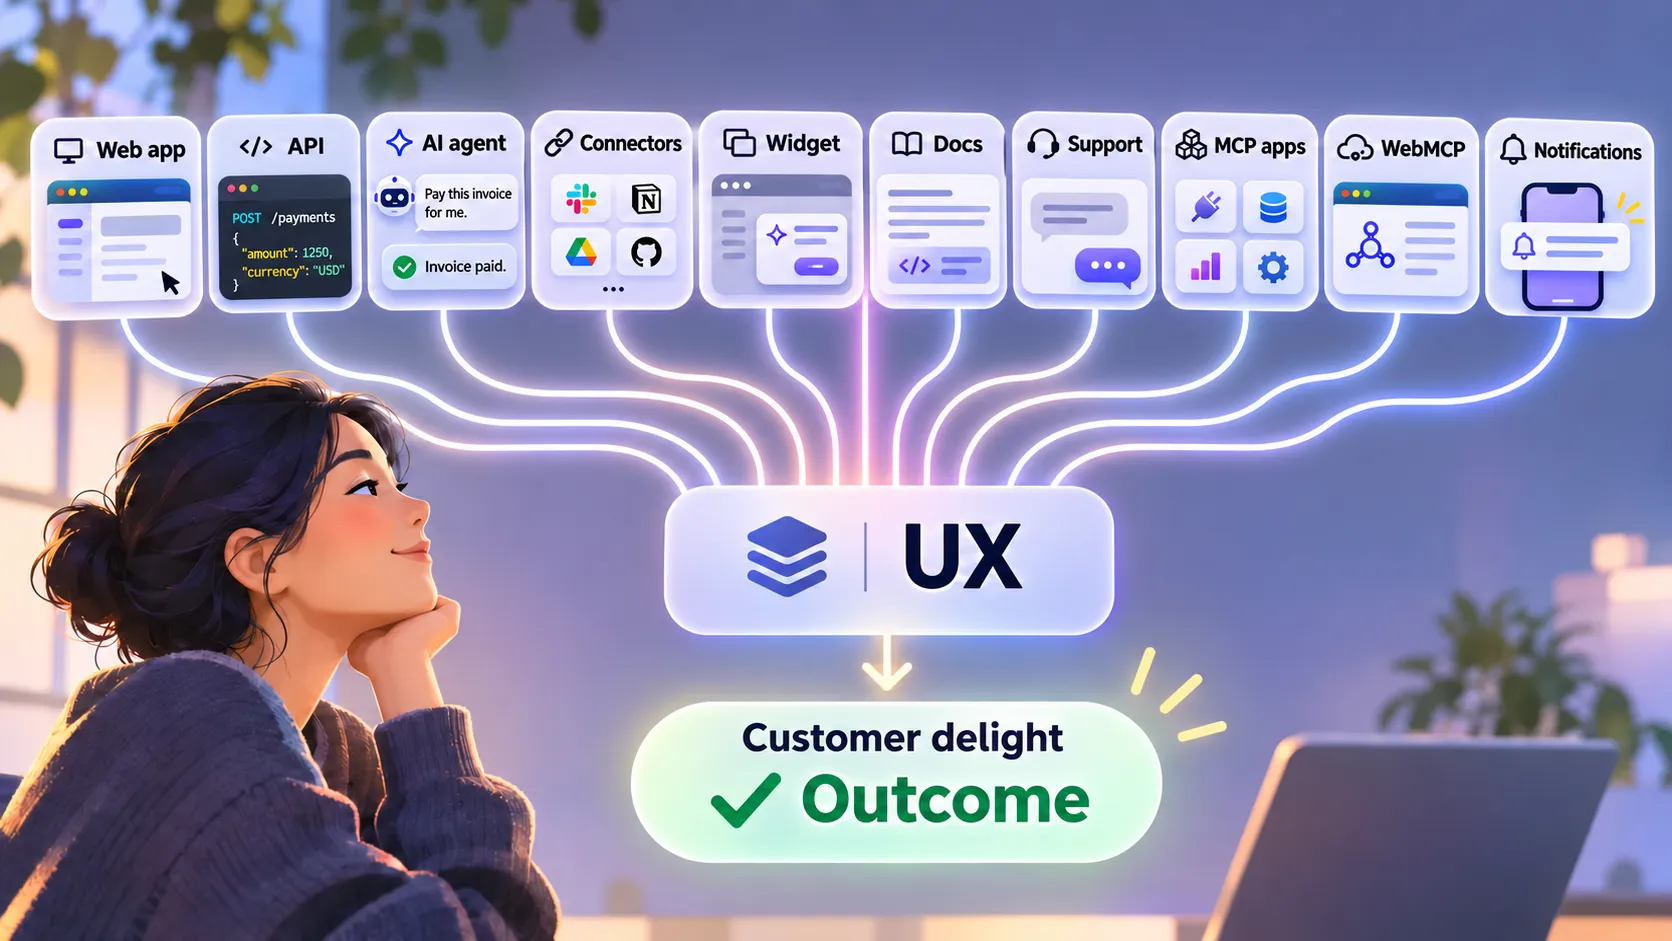
Customers reach you through your web app, API, AI agents, connectors, widgets in partner apps, docs and support. You reach them through notifications. Hire UX people who can understand and influence all of it.
Start everyone on Gemini. Move people who keep asking engineers questions to Claude Tag in Slack. Give a Claude seat to the people who build things or do long, private work, inside engineering or outside it.
That approach keeps you out of two traps: seats nobody opens, and staff stuck on a tool that can’t do their job.
In twenty years I’ve watched people grow into leaders, helped a few get there, and grown into the role myself. How far each of us got depended on the trust, backing and incentives around us as much as on what we brought.
Before you say yes to a lead role, find out who will stand behind you when the decisions get hard.
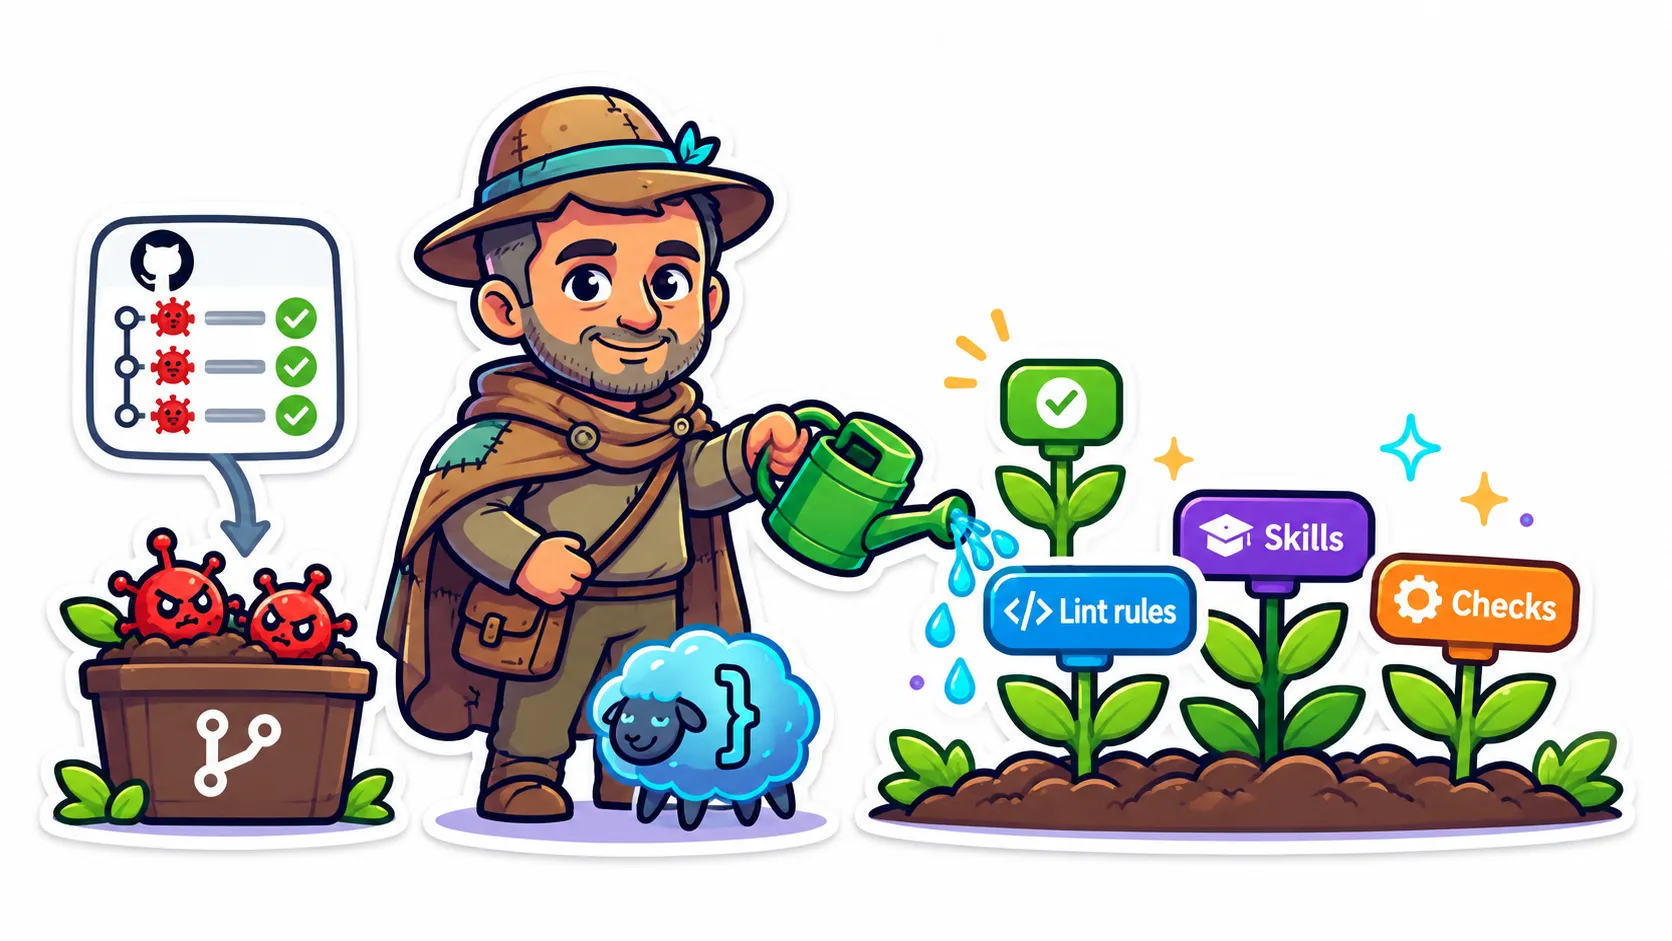
Your coding agents repeat mistakes you corrected last week. A gardener reads what your team accepted on recent pull requests each week and proposes a lint rule or a sharper instruction when the evidence supports one.
The gardener opens each proposal as a PR with its evidence, and you decide whether it merges.
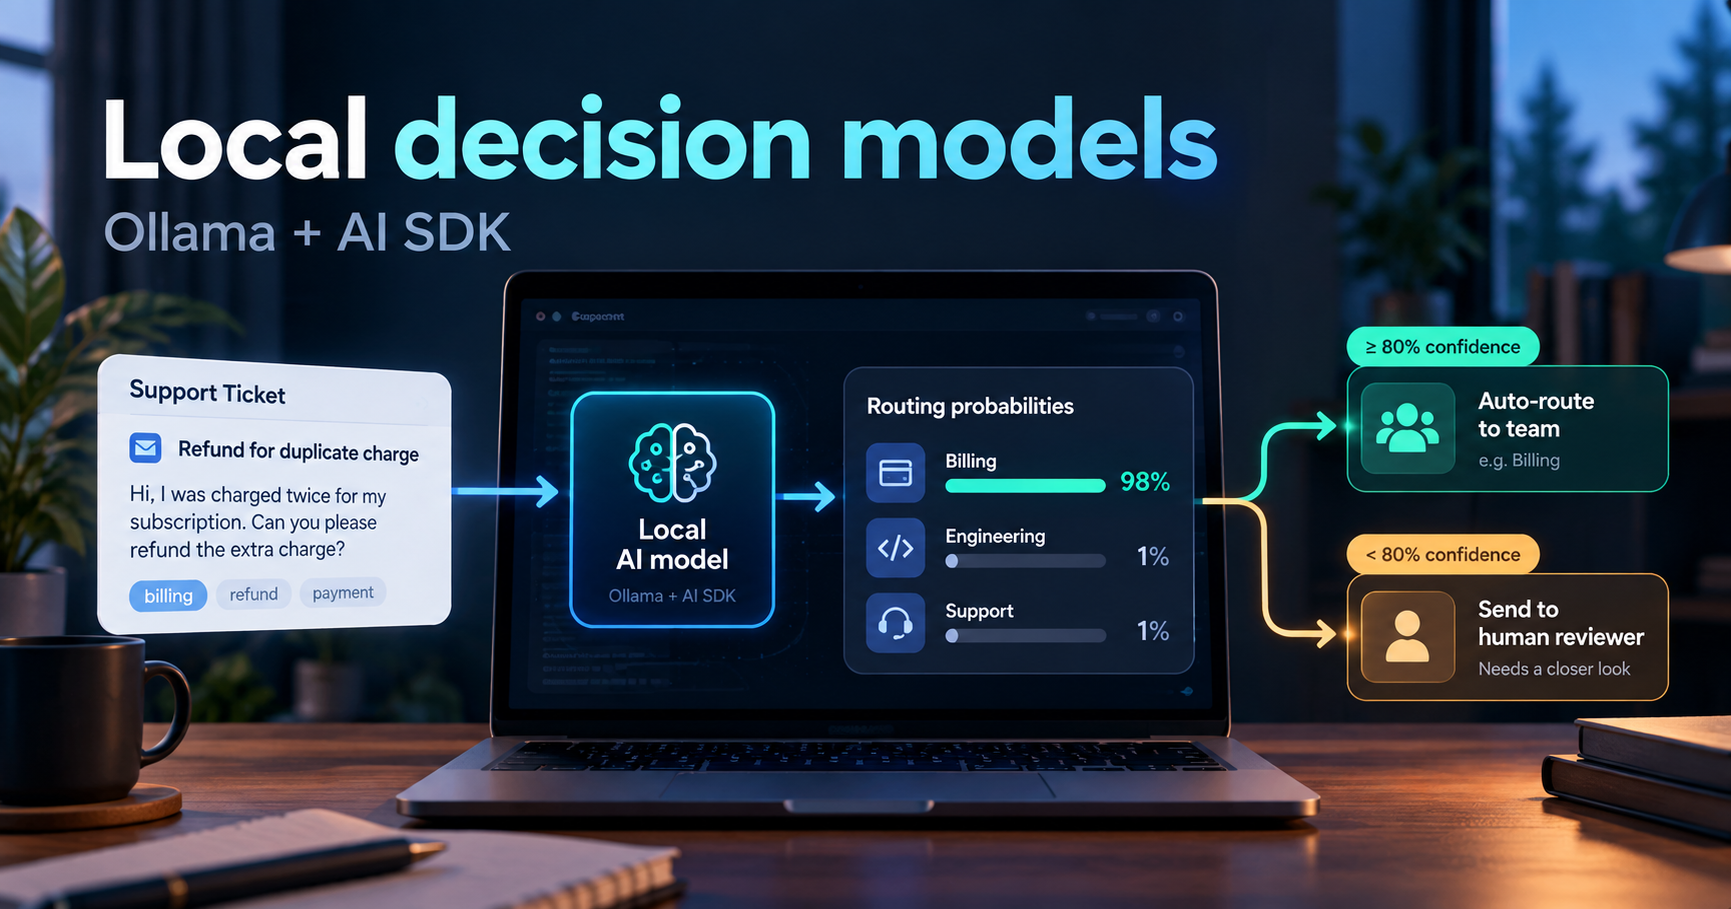
Ollama 0.35 runs decision models on your own computer. You give one a support ticket and a question like “which team should handle this?”, and it returns a percentage for each team instead of writing a reply.
I ran 12 support tickets through the three new models and a small chat model on a MacBook Pro.
The decision models routed every clear ticket correctly.
On the tickets I wanted a person to check, two of the three models still sounded sure, and that changes how you set the rule that hands work to a human.