Your coding agents need a gardener
19 Oct 2026Your coding agents repeat mistakes you corrected last week. A gardener reads what your team accepted on recent pull requests each week and proposes a lint rule or a sharper instruction when the evidence supports one.
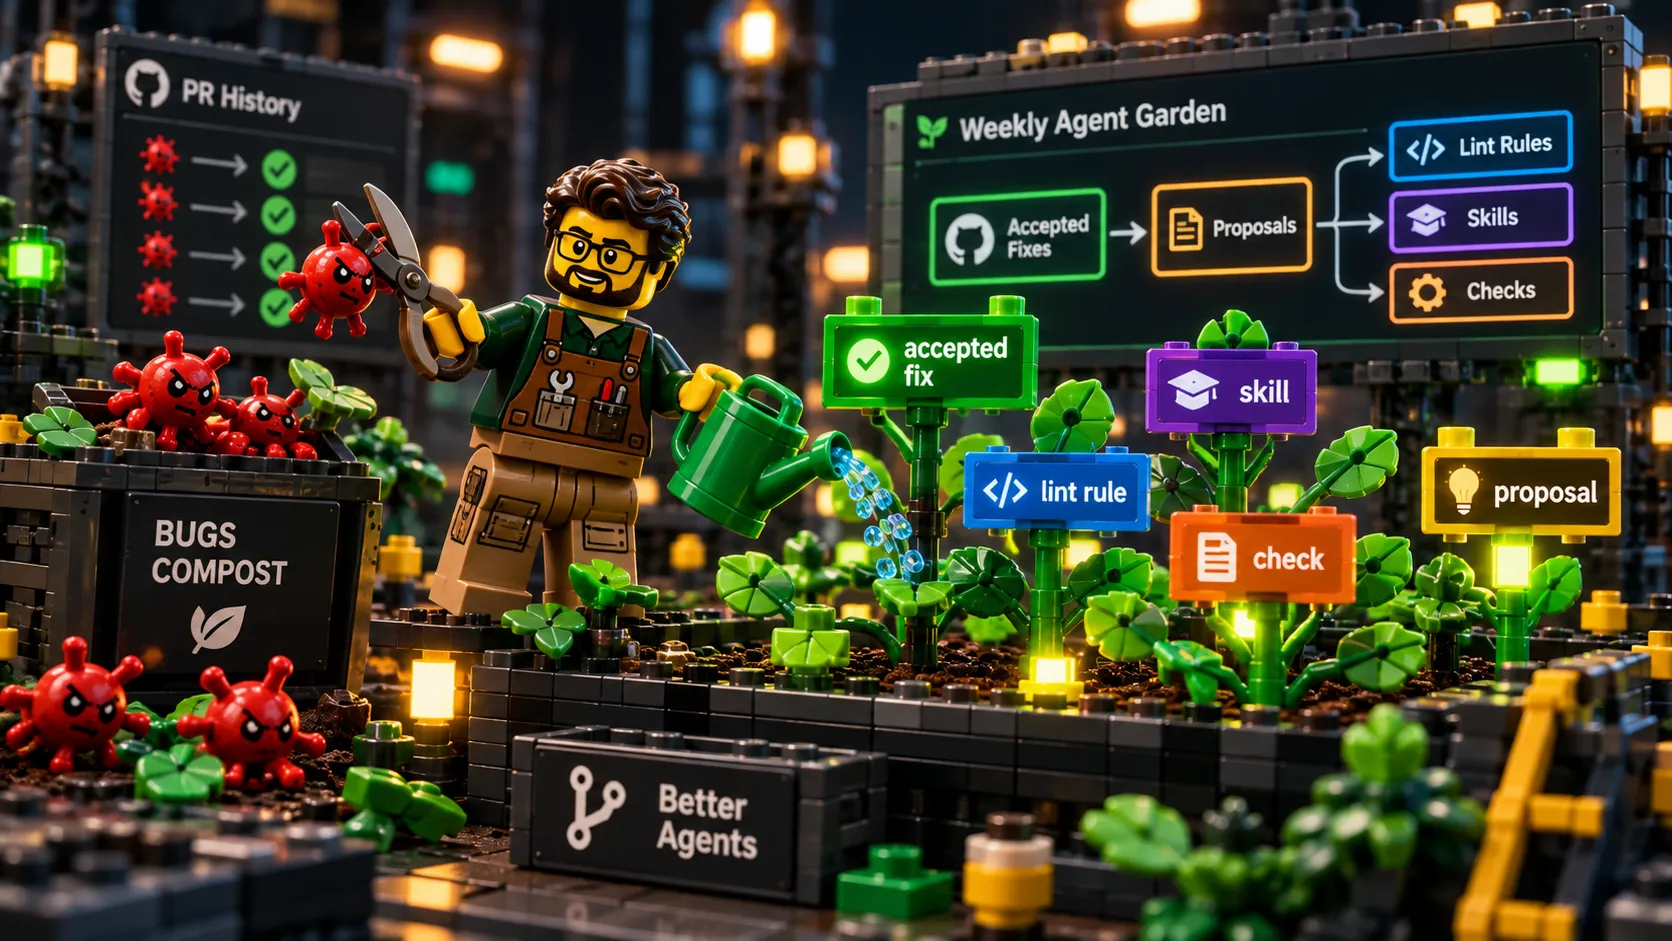
The gardener opens each proposal as a PR with its evidence, and you decide whether it merges.
You correct an agent on Monday. On Thursday a fresh session makes the same mistake, because nothing it reads has changed. You spent your attention on that correction twice, and you’ll spend it again next week.
Ben Holmes described a useful split. Product engineering improves the product. Factory engineering improves the agents that improve the product. He credits @poteto with calling that second kind of work “gardening”. His example is an outer loop that scores agent conversations and uses the results to suggest skill changes.
Rachel Laycock’s The Conductor Developer argues that faster agents make human attention the scarce resource. In her account, a developer directs the work and judges what comes back.
Put the two together and you get the number I optimise for: how much of your attention the agents use. I count how often an agent asked something the repository answers, and how much context you needed before you could answer an escalation. A good hand-back names the decision and shows the evidence. I’d take a precise question about a real trade-off over a quiet guess, so I aim for better questions, which sometimes means more of them.
Three loops
---
alt: "Shepherd runs review rounds inside a coding agent, then repairs CI and reads Stamp’s approval verdict. Both record their work on GitHub and export traces. The weekly gardener reads those records and incidents traced to PRs Stamp approved, then proposes skill edits or checks for a person to review."
---
flowchart LR
  subgraph inner["Shepherd: in your coding agent"]
    S["Swarm<br/>reviews the diff"] --> T["Triage<br/>fixes or defers threads"]
    T --> SI["Simplify"]
    SI --> S
  end
  inner --> C["CI repair"]
  C --> ST["Stamp in CI<br/>gates + model review<br/>approves or refuses"]
  ST --> GH[("GitHub record<br/>threads, commits,<br/>statuses, verdicts")]
  inner --> GH
  inner --> TR[("Traces<br/>stages, retries, waits")]
  ST --> TR
  TR --> G["Gardener, weekly<br/>scores reviews, traces and incidents"]
  GH --> G
  G --> P["PRs that change<br/>skills and lint rules"]
  P -. next run .-> inner
My implementation has three parts, each with one kind of authority:
- Shepherd runs in your coding agent. It reviews a PR and fixes what it can, including the build.
- Stamp runs in CI and decides whether the result earns an approval. It never changes code.
- The gardener runs once a week. It reads the GitHub record, plus traces when you configure a source, and proposes changes to Shepherd’s skills and the repository’s lint rules. You decide whether to merge them.
Shepherd fixes the PR, Stamp approves it covers the first two in detail.
Count what your team accepted
You can inspect the gardener’s evidence on GitHub after the coding-agent session ends. For each recent PR Shepherd touched, it collects the review threads, Shepherd’s commits and their trailers, any reverts of those commits, the shepherd commit status, and the swarm summary’s round count. I score that record with these signals:
| Signal | Raised when |
|---|---|
reverted_fix |
someone reverted a commit Shepherd made |
human_replied |
a person replied in a Shepherd thread |
round_cap |
the review loop ran four rounds without settling |
stopped_short |
the loop ended needing the author |
loop_stalled |
Shepherd committed, then the head went a day with no final status |
churn |
Shepherd made more than ten commits on one PR |
For each signal, the garden skill reads the linked thread or commit before proposing an edit. It names the sentence in a skill that would change, or concludes that the skill did its job. A human_replied signal where the person agreed with the finding counts as Shepherd getting it right, though it never counts as an accepted fix. An escalation the author settled the way Shepherd framed it counts as Shepherd working, because asking at the right moment is part of the job.
A proposal is as good as its evidence, so the gardener sets a strict test for acceptance. Triage names each rule it fixes in a Shepherd-Fixes commit trailer. The gardener counts those trailers, taking them only from commits nobody reverted, on PRs by people who can push to the repository. A resolved thread on its own counts for nothing, because triage also resolves findings it judges mistaken.
Built this way, a proposal records what your team chose to do. Merge it, and the next agent session reads the revised instruction or runs the new check. A finding your team rejected gets no lint rule, however many threads triage resolved.
One run, one proposal
I ran the first garden over fourteen PRs on my test repository. Shepherd had touched eleven of them, which gave me plenty of signals to read.
The gardener compared each signal’s date with the history of Shepherd’s skills. Later skill changes covered most of what it found, so it dropped those. It proposed one edit: a sentence in triage’s rule for instructions from the person running Shepherd, backed by the thread that showed the need. It also named the reading under which a maintainer might decline it.
You can judge a proposal of that size in a minute. I wanted a gardener that proposes little, with evidence, over one that rewrites prompts every week.
Check or instruction
Before it writes anything, the gardener sorts each cause with the categories from Matt Pocock’s retro skill, which Shepherd ships unchanged:
- A mechanical mistake gets an automated check.
- An existing check nobody wired in gets reported as missing wiring.
- A judgement call gets skill text, written with his
writing-for-agentsskill.
Prefer the check. A lint rule runs the same way every time and costs nothing to read. An instruction asks a model to remember, and the model reads it alongside everything else in its context.
Some decisions need context. An interface with one implementation can be a boundary worth keeping, and a reviewer should weigh that argument case by case. A pattern one file’s syntax can decide works better as a lint rule. A machine can check for a class whose only method forwards to one collaborator, or a filter().map() chain, and then Shepherd’s checks report it before any model reads the diff.
The gardener proposes a lint rule when triage fixed the same finding on at least three PRs:
---
alt: "A model reviewer flags a pattern. A person accepts the fix, recorded as a Shepherd-Fixes trailer. After three accepted fixes on separate PRs, the gardener proposes a lint rule with the accepted cases it must flag and a counterexample it must leave alone. The rule starts as a warning in the repository's Oxlint plugin."
---
flowchart LR
  J["Model reviewer<br/>flags a pattern"] --> A["You accept the fix<br/>Shepherd-Fixes trailer"]
  A --> R["Three accepted fixes<br/>on separate PRs"]
  R --> L["Gardener proposes a lint rule<br/>cases it must flag,<br/>a counterexample it must allow"]
  L --> W["Rule ships as a warning"]
The proposal includes the accepted cases the rule must flag and a counterexample from the repository it must leave alone. New rules start as warnings in the repository’s vendored Oxlint plugin. A rule that needs the whole repository, such as “this interface has one implementer”, stays with the reviewers. Each warning takes a moment of each author’s attention, so keep a rule when it catches a mistake your team cares about and explains the fix.
An agent chasing a green build can add oxlint-disable above the line and move on. Shepherd and Stamp both list each suppression comment a PR adds. Stamp’s reviewer reads the code each one covers, refuses a suppression that hides a finding the change introduced, and approves a narrow one that gives its reason.
Learn from a regression Stamp approved
A PR can pass review and introduce a production bug. Shepherd’s /incident skill takes a failed build or a production error and tries to reproduce it in a test. It checks which PR introduced the failure, records whether Stamp approved that PR, and opens a fix PR. Without a reproducing test, Shepherd stops short of claiming a fix.
The gardener reads those incident issues as a separate escapes list. For each one, it inspects the culprit diff and Stamp’s review, then the fix and its reproducing test. It proposes a rule that flags the culprit change and allows the fix. A syntax check goes into the repository’s lint plugin; a check that needs judgement goes into an existing Stamp rule pack or Shepherd lens.
An escaped regression supplies a reproducing case, so the gardener can propose a check from that one incident. The three-PR threshold applies to recurring review findings. You can inspect the failure that prompted either proposal.
Some incidents come from combining branches that passed on their own. For those, the gardener recommends up-to-date branches or a merge queue. It proposes no review rule for a failure the reviewed diff could not show.
Shepherd can use executable-stories to keep the incident’s ticket beside the reproducing scenario. Its fix workflow compares full current and base runs, checks that the ticket’s scenarios pass, and flags skipped or shortened scenarios. Stamp refuses a PR that closes an incident issue without a test that reproduces the failure. You can follow the issue from the failure through the test, fix and proposed rule.
Keep the gardener’s power small
The weekly workflow splits reading from writing. The agent that reads the record has read-only tokens and writes its proposals to an outbox. A separate job on a fresh runner applies each patch to a clean clone with Git hooks off, accepts only changes outside .github and .git, and opens the PR.
Stamp reviews the gardener’s PRs under the repository’s existing policy. A PR that edits .stamp/ or a configured rule pack goes to a person, because later reviews trust those files. For other skill changes, Stamp’s reviewer checks for removed lenses, narrowed scope and weakened rules.
Your team controls Shepherd’s fix permissions and checks through .shepherd/config.yml. Shepherd reads that policy from the default branch. You can preview a proposed policy edit before merging it, including the commands, reviewers and steps that can write code or touch GitHub.
Find expensive or stalled runs
Shepherd and Stamp export traces through autotel when you set an OTLP endpoint. The gardener can add those traces to its GitHub evidence from OTLP JSON exports, Grafana Tempo or Datadog. It matches each trace to the repository, the PR and a commit on that PR, and counts a span once when exports overlap.
The report flags four measurements for investigation:
| Signal | Default trigger per PR |
|---|---|
trace_stage_failed |
A recorded stage failed or never finished |
trace_retries |
At least three recorded retries |
trace_approval_wait |
At least five minutes and half the observed iteration time waiting for approval |
trace_review_cost |
At least $5 of known Stamp review cost |
You can change the retry, wait and cost thresholds. Each report records the thresholds it used and trace IDs you can inspect. Stamp records review cost; Shepherd records orchestration time. To measure what the coding agent spent, you need usage from its harness.
For a file export, run:
bunx @jagreehal/shepherd garden acme/service --since 2026-10-01 \
  --traces /var/lib/otel/garden.jsonl
For Tempo, configure GARDEN_TEMPO_URL and read-only headers in GARDEN_TEMPO_HEADERS. For Datadog, configure GARDEN_DATADOG_SITE, GARDEN_DATADOG_API_KEY and GARDEN_DATADOG_APP_KEY, with apm_read access. The setup guide covers each source. In the scheduled workflow, a collector step holds the backend credentials and hands the agent a report file through GARDEN_REPORT, so the agent reading untrusted PR text never holds them.
Sampling and retention leave gaps, and the report says where: unavailable reads, searches cut short, partial results from Datadog and unpriced reviews. It also counts PRs with traces that Shepherd did not work on. A missing price stays unknown, and the report labels its numbers as observed samples.
The gardener checks GitHub for the cause before proposing an edit. A long approval wait might call for a workflow change, or the author might have needed time to decide. Crossing the cost threshold flags a run for you to inspect. Accepted fixes need unreverted Shepherd-Fixes trailers and the author checks described above, whatever the traces show.
Next
Both tools use executable stories for tests of their review mechanics. Stamp’s scenarios check that it withdraws stale approvals and removes an older approval after a newer refusal. Shepherd’s scenarios check that a fix invalidates its previous review receipt and that skipping a test cannot verify a fix. Those tests protect the implementation. Next I want a set of representative agent tasks to rerun against a revised skill, so I can check that a new instruction changes what the agent does.
For a garden PR, I want the correction that prompted it, a case the new check catches and one it leaves alone. You decide whether those cases justify the change. After you merge it, Thursday’s session reads the instruction you had to explain on Monday.